Live Online Bootcamp
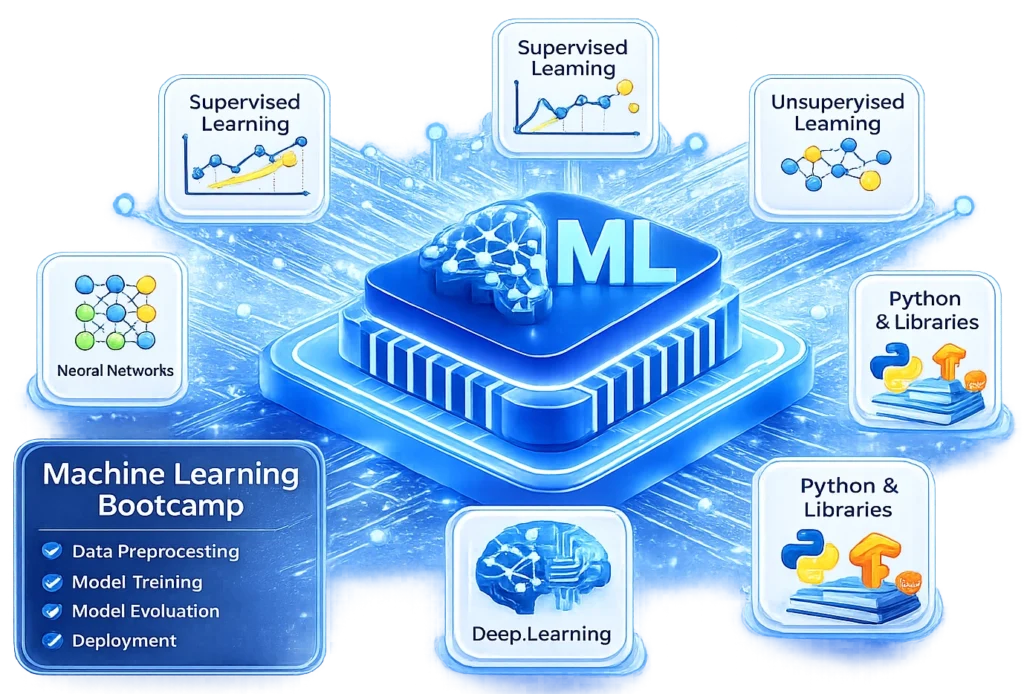
Machine Learning Bootcamp
Live Online Training
Cohort Cap: 20 Students
3 Capstone Projects
Industry Certificate
Trusted by Learners & Professionals from Top Companies
WHY LEARN MACHINE LEARNING TODAY?
The Skill That Defines Modern Data Careers
- ML remains the technical core of the most valued data careers in the US
- Every industry needs predictive models on their own data — LLMs alone can't do it
- Move from Python-comfortable to job-ready ML practitioner in 12 weeks
- Build 3 real capstone projects your GitHub can actually show
- Direct instructor code review — impossible in mega-cohort courses
WHAT YOU'LL LEARN
Supervised Learning
Unsupervised Learning
Feature Engineering
Model Evaluation & Cross-Validation
Scikit-Learn Mastery
Gradient Boosting (XGBoost / LightGBM)
Deployment Basics (Flask / FastAPI)
End-to-End Real-World ML
TOOLS & LIBRARIES YOU'LL MASTER
Python
The core language of ML
Scikit-Learn
The standard ML toolkit
Pandas
Data preparation for ML
NumPy
Numerical foundation
XGBoost
Industry-standard gradient boosting
LightGBM
Fast gradient boosting from Microsoft
CatBoost
Categorical-friendly gradient boosting
Matplotlib
Model diagnostics and visualization
Seaborn
Statistical visualization
Jupyter
Standard ML workbench
Git & GitHub
Portfolio and version control
Flask / FastAPI
Deploying models as APIs
COURSE CURRICULUM
01
02
03
04
05
Week 1
Linear & Logistic Regression
- ML workflow fundamentals
- Linear regression from first principles
- Logistic regression for classification
- Regularization (L1, L2)
- Reading model diagnostics
Week 3
Trees & Ensembles
- Decision trees
- Random forests
- Gradient boosting (XGBoost, LightGBM, CatBoost)
- Handling categorical features
- Interpretability with SHAP
Week 5
Unsupervised Learning
- K-means clustering
- Hierarchical clustering
- DBSCAN
- Principal Component Analysis
- Anomaly detection intro
Week 8
Evaluation & Feature Engineering
- Cross-validation strategies
- Precision, recall, F1, ROC-AUC
- Hyperparameter tuning
- Feature engineering patterns
- Avoiding data leakage
Week 11
Deployment Basics
- Model serialization (joblib, pickle)
- Building prediction APIs (Flask/FastAPI)
- Docker basics
- Git workflows for ML projects
- Introduction to cloud deployment
What You Will Learn
The Twelve-Week Curriculum
The curriculum is organized into four major arcs across twelve weeks. Each arc builds on the previous one, and the course as a whole is structured around three capstone projects rather than passive coverage of material.
The first arc covers the supervised learning algorithms that form the working core of most production ML systems in the US. Each algorithm is introduced with the intuition first, then the underlying mathematics at an applied level, then the working code. Learners do not just call model.fit() — they understand what is being optimized, why, and what can go wrong.
Algorithms covered in depth include linear regression, logistic regression, decision trees, random forests, gradient boosting machines (XGBoost, LightGBM, CatBoost), and support vector machines at a working level. The arc also covers how to split data correctly, how to avoid data leakage (the single most common failure mode in real ML projects), and how to set up reproducible training pipelines.
The arc ends with Capstone 1: a complete supervised learning project on a real US dataset.
You will Explore
Linear & Logistic Regression
Decision Trees & Random Forests
Gradient Boosting Deep Dive
Reproducible Training Pipelines
The second arc covers the unsupervised methods that find structure in unlabeled data — increasingly important in customer segmentation, fraud detection, anomaly monitoring, and exploratory analysis at scale.
Topics include K-means clustering, hierarchical clustering, DBSCAN, principal component analysis, t-SNE and UMAP for high-dimensional visualization, and an introduction to anomaly detection using statistical and ML-based approaches. The arc emphasizes interpretation alongside technique — unsupervised methods produce results that look meaningful even when they are not, and learning to evaluate unsupervised output honestly is a key skill.
You will Explore
K-Means & Hierarchical Clustering
DBSCAN & Density Methods
PCA & Dimensionality Reduction
Anomaly Detection
The third arc is the most practically intensive. It covers the working patterns that distinguish junior ML practitioners from senior ones: rigorous evaluation, careful feature engineering, and the disciplined use of scikit-learn pipelines.
Topics covered include scikit-learn pipelines for building reproducible, leak-free training workflows; cross-validation strategies (k-fold, stratified, time-based); hyperparameter tuning; evaluation metrics in depth (accuracy, precision, recall, F1, ROC-AUC, RMSE, MAE, R², log loss); feature engineering patterns; handling imbalanced data; and the discipline of avoiding data leakage as a dedicated topic.
The arc ends with Capstone 2: a modeling project with careful evaluation, feature engineering, and a written technical report.
You will Explore
Scikit-Learn Pipelines
Cross-Validation Strategies
Feature Engineering Deep Dive
Metrics That Actually Matter
The fourth arc moves from notebook-based ML to the basics of getting models into production. Topics include model serialization with joblib and pickle; building prediction APIs with Flask and FastAPI; introduction to containerization with Docker; basic logging and monitoring for deployed models; working with cloud platforms at an introductory level; and Git workflows for ML projects.
Model Serialization & Packaging
Flask & FastAPI for ML
Docker Basics for ML
Cloud Deployment Intro
The final two weeks are dedicated to Capstone 3: a complete machine learning project taken from problem definition through deployment, presented in the final session and added to the learner's professional portfolio.
Three Capstone Projects
Build • Evaluate • Deploy
Not one capstone — three. A supervised learning project by Week 4, a rigorous modeling project by Week 9, and a full deploy-ready pipeline by Week 12. Every capstone is code-reviewed by the instructor and added to your GitHub.
By the end of twelve weeks, you'll have three real projects worth showing hiring managers — not just a certificate.
REAL-WORLD PROJECTS
Customer Churn Predictor
Build a churn model on real telecom-style subscription data.
Loan Default Risk Scorer
Full modeling project on public lending data.
Demand Forecasting
Time-aware feature engineering and forecasting for retail.
Fraud Detection
Class-imbalanced classification with proper evaluation.
Full Deploy Pipeline
End-to-end capstone: model + API + Docker + written report.
Course Format and Delivery
The Machine Learning Bootcamp is the flagship technical program at Mindvex, delivered fully online through live, instructor-led sessions.
01
Schedule
Four live sessions per week over twelve weeks, in evening and weekend slots that work for working professionals across US time zones.
- Each session runs approximately 90 minutes.
02
Cohort Cap: 20 Students
The cap exists so every learner gets direct instructor feedback on code, capstones, and individual progress. This is one of the most important structural features of the program.
- Small cohort. Real feedback.
03
Industry Mentor Q&A
Scheduled sessions with working ML practitioners from US employers. Not marketing events — structured conversations that cover interview prep, on-the-job realities, and how hiring teams actually evaluate ML candidates.
- Learn from practitioners who hire.
04
Code Reviews on Every Capstone
Each of the three capstones receives written code review from the instructor covering code quality, modeling choices, evaluation rigor, and technical writing.
- Ship-quality feedback.
05
GitHub Portfolio
Every capstone pushed to GitHub. Graduate with a real public portfolio that hiring managers can inspect directly.
- Build a portfolio. Get interviews.
Prerequisites and Technical Requirements
This is an intermediate course. Prerequisites are real:
Working Python — functions, Pandas DataFrames, NumPy arrays, basic Matplotlib
Familiarity with basic statistics (means, distributions, correlation)
Laptop with 16 GB RAM recommended, modern OS, stable internet
Plan for 12–15 hours per week (4 live sessions + independent practice)
Why Machine Learning Skills Matter In The Us Job Market
Still the Technical Core of Data Careers.
Machine learning engineer, data scientist, applied scientist, and AI engineer remain among the highest-compensated technical roles in the US. Every serious data organization needs practitioners who can build, evaluate, and deploy models — not just call LLM APIs.
Broad Industry Demand.
Unlike some AI specializations concentrated in a handful of companies, ML skills are needed across US technology, finance, healthcare, retail, insurance, and virtually every industry that has data and decisions to make. This breadth is what makes ML the safest specialization in the AI job market.
Compensation That Reflects the Skill.
Entry-level ML roles in major US metros commonly start in the high five-figure to low six-figure range. Mid-career practitioners regularly reach mid-six-figure totals, with senior practitioners at larger employers earning significantly more. Demonstrated portfolio work — not just credentials — is what unlocks these ranges.
Learn From Industry Leaders
Michael Anderson
Lead Instructor — AI & Cloud
- AWS Certified
- 10+ Years Industry Experience
- Published AI Researcher
Senior AI engineer with extensive experience designing machine learning platforms and deploying enterprise AI solutions.
David Miller
Cloud & MLOps Instructor
- Cloud Architect
- Google Cloud Certified
- Enterprise MLOps Specialist
Cloud Architect specializing in scalable AI infrastructure, MLOps automation, and multi-cloud deployments for enterprise.
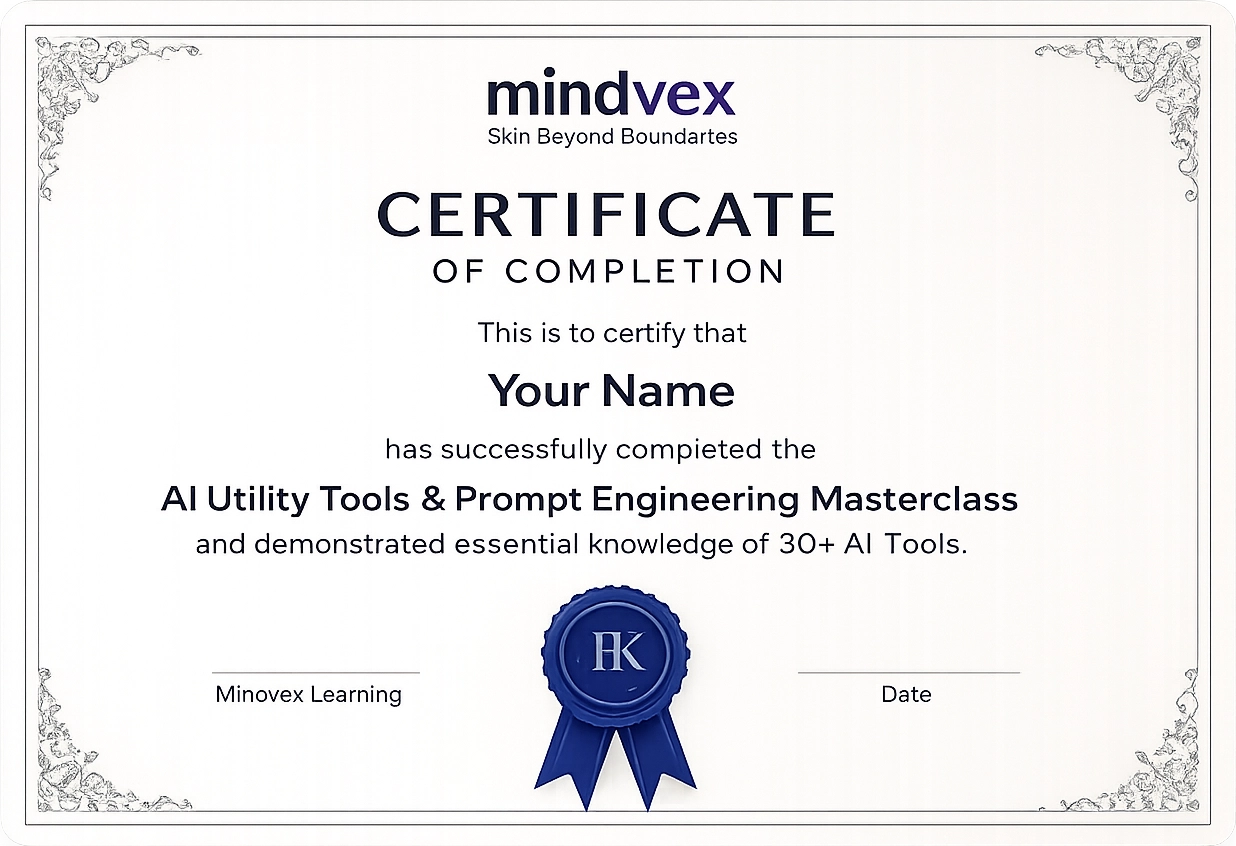
INDUSTRY RECOGNIZED CERTIFICATE
Receive an industry-recognized certificate after successful bootcamp completion.
- Industry Recognized
- LinkedIn Shareable
- Verifiable Certificate
- Career Boost
Career Impact
What Our Learners Say
The AI for Data Analytics course gave me the exact tools needed to interpret complex data streams quickly. The practical framework for integrating modern AI directly into existing analytical workflows was immediately applicable.
The multi-agent simulations in the Advanced Python for LLM & Multi Agent Systems course completely transformed our engineering team's approach to complex system design. Exceptional depth and real-world utility.
Enrolling our product team in Agentic AI & Multi Agent Autonomous Systems provided the strategic edge we were missing. The hands-on project structures made deploying autonomous agents far more straightforward.
After taking NLP with LLMs, I was able to fine-tune and deploy a custom retrieval-augmented model in weeks. The instructors cover production-grade deployment strategies that you rarely find in standard online courses.
The Executive Diploma in Deep AI & Cloud Intelligence offered a clear, high-level strategic overview without glossing over technical rigor. It helped our leadership team align our enterprise cloud architecture with modern AI solutions.
Bridging the gap between prototype models and production infrastructure can be tough, but MLOps & AI in Production laid out the best practices clearly. Highly recommended for any engineering group scaling AI services.
Ready To Become An ML Practitioner?
Join a cohort of committed learners building real ML careers.
Frequently Asked Questions
Structural differences: cohort cap of 20 students, four live sessions per week, three real capstone projects with direct code review, and industry mentor Q&A sessions. Many advertised bootcamps are largely pre-recorded video with limited live interaction. This bootcamp is built around live instruction and direct feedback because that consistently produces graduates with employable skills.
For most learners, yes. Self-paced courses rarely produce the depth of hands-on practice and direct feedback that a structured live bootcamp does. The fastest way to know: try one of the capstone-style projects on your own. If you can complete it end-to-end with confidence, you may not need the bootcamp. If you cannot, the bootcamp is built for exactly that gap.
The bootcamp itself does not include a job guarantee. The AI Full Career Track Bundle, which includes the bootcamp as one component, offers an optional Job Guarantee add-on.
Yes, and most learners do. Sessions are scheduled in evening and weekend slots. The honest time commitment is 12–15 hours per week. Learners who cannot sustain that should consider scheduling the bootcamp during a less demanding period at work.
Start Your ML Career Today!
Cohort cap 20. Seats fill weeks in advance. Reserve yours now.
- Live Cohort of 20
- 3 Capstone Projects
- Industry Mentor Q&As
- Job-Ready Portfolio